Overview
Fireworks is an OpenAI-compatible provider in Bifrost with native support for:- Chat Completions via
/v1/chat/completions - Responses API via
/v1/responses - Text Completions via
/v1/completions - Embeddings via
/v1/embeddings - Streaming for chat, responses, and completions
- Tool calling for chat and responses
- Optional Anthropic-compatible mode via
/v1/messages, enabled per key or per alias withuse_anthropic_endpoints
Supported Operations
By default, Fireworks Responses support is native in Bifrost. Requests are sent to Fireworks’
/v1/responses endpoint directly, so fields such as previous_response_id, max_tool_calls, and store are preserved. With use_anthropic_endpoints on, Responses are converted to the Anthropic Messages format instead, and those Responses-only fields do not apply.Setup & Configuration
Configure Fireworks as a provider.- Web UI
- config.json
- API
- Go SDK
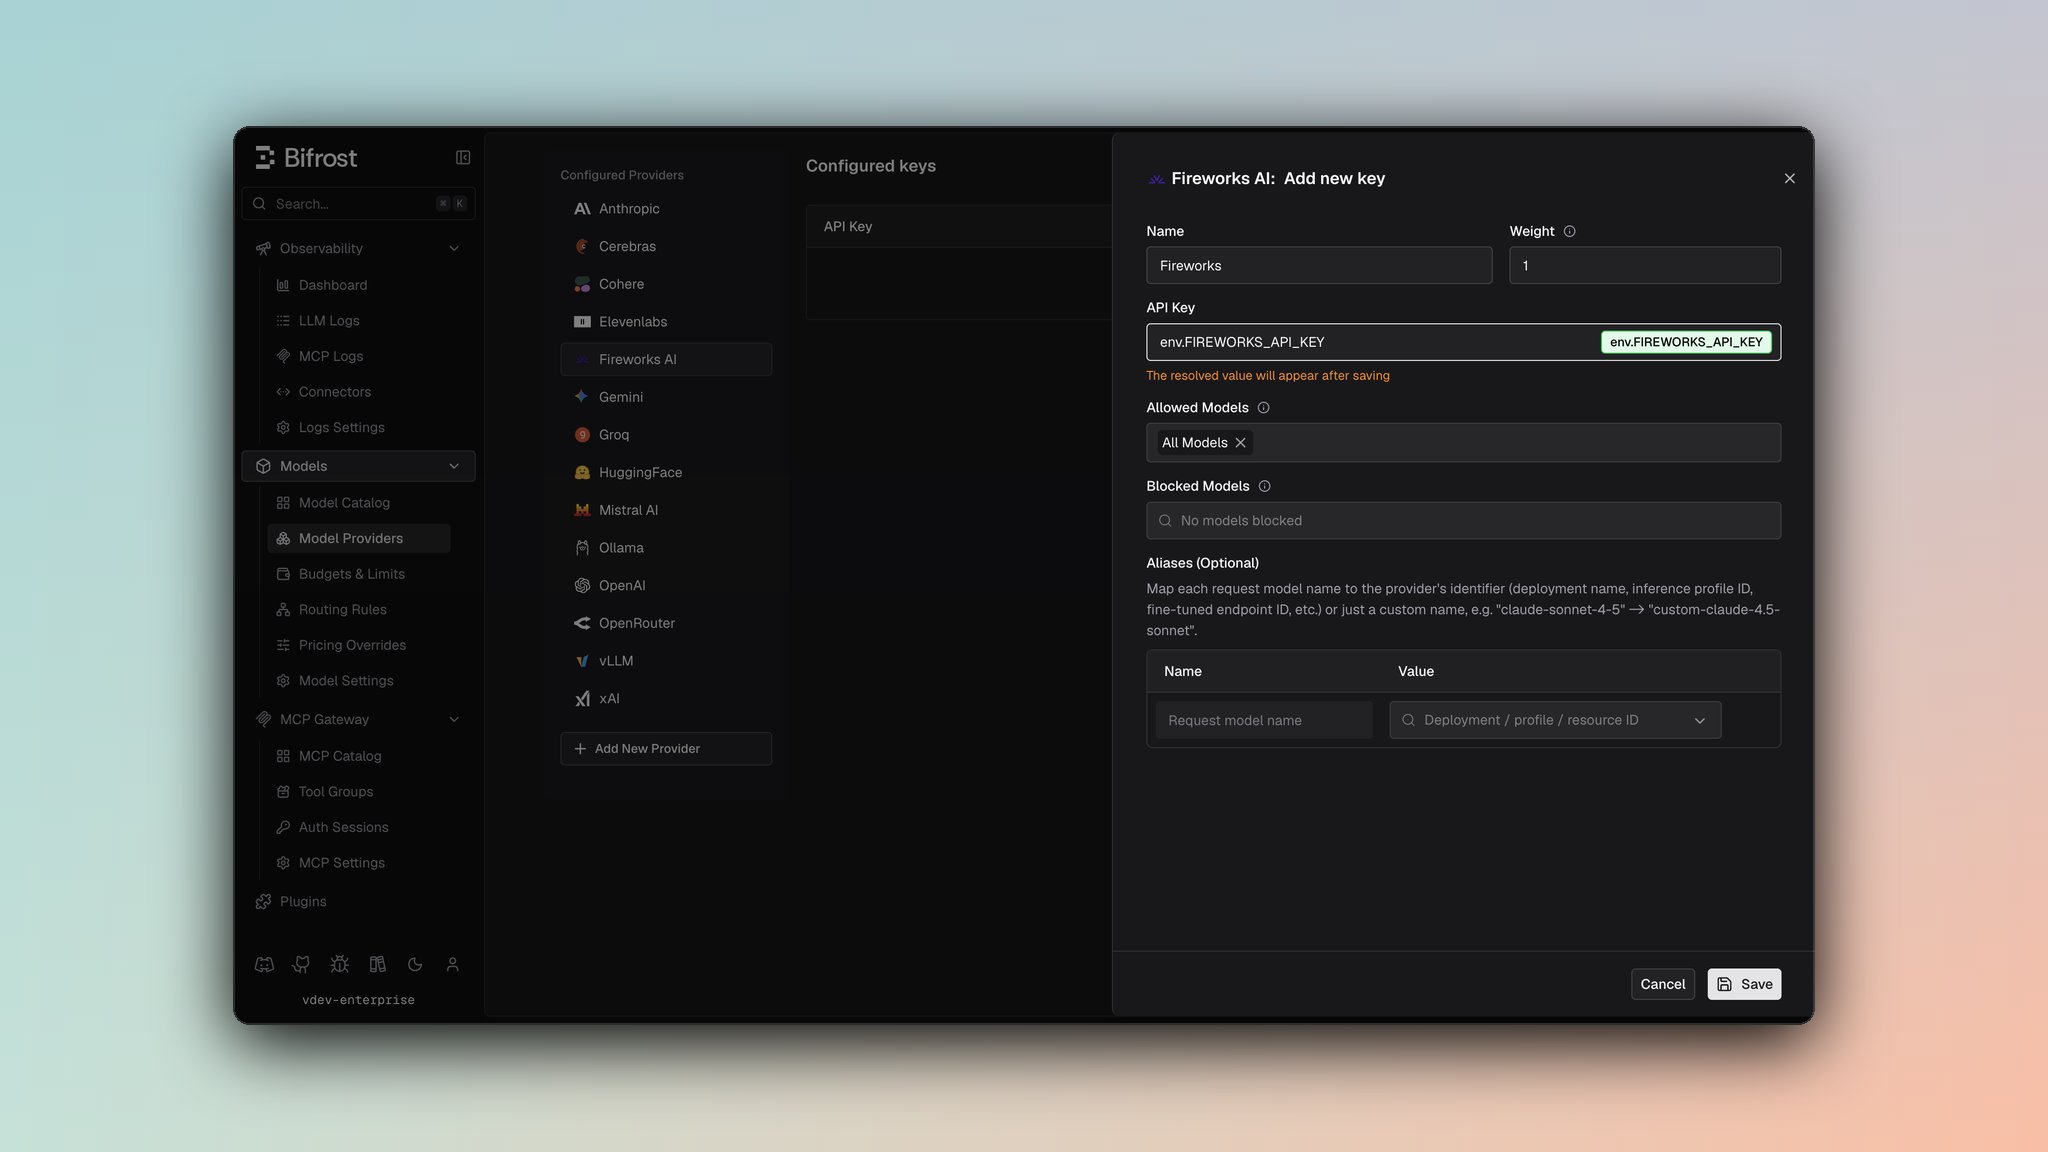
- Navigate to Models > Model Providers. Look for Fireworks under Configured Providers. If it is missing, click on Add New Provider and select Fireworks.
- Click Add Key or edit an existing key.
- Set a name for your key.
- Paste your API key directly or use an environment variable (for example,
env.FIREWORKS_API_KEY). - Set Allowed Models to All Models (default) or the specific model allowlist you want this key to serve.
- Save the provider configuration.
Anthropic-Compatible Endpoints (optional)
Fireworks exposes an Anthropic-compatible Messages endpoint (/v1/messages) alongside its default OpenAI-compatible APIs. Setting use_anthropic_endpoints routes Chat Completions and the Responses API through that endpoint instead. Text Completions and Embeddings are unaffected and always use their OpenAI-compatible endpoints.
Authentication does not change between the two modes: Bifrost sends Authorization: Bearer <key> either way.
The setting can be configured per key, and overridden per model alias:
- Key-level - Sets the default endpoint mode for every request made with that key.
- Alias-level - Overrides the key-level default for a single alias, so one key can serve some aliases through the OpenAI-compatible endpoints and others through the Anthropic-compatible endpoint.
- Web UI
- API
- config.json
On the key form, toggle Use Anthropic Endpoints (off by default). To override this for a specific alias, open that alias’s expanded row in the deployments table and toggle Use Anthropic endpoints under Fireworks overrides, which takes priority over the key-level setting for that alias only.
1. Chat Completions
Fireworks chat completions use the standard OpenAI-compatible wire format.Fireworks-specific handling
predictionis preserved and forwarded.- Bifrost maps
prompt_cache_keyto Fireworksprompt_cache_isolation_keyfor chat-completion cache isolation. - Assistant
reasoning_contentis preserved for Fireworks chat-completion models that support reasoning history.
Filtered Parameters
For Fireworks chat completions, Bifrost removes or rewrites a small set of OpenAI-specific fields before sending the request upstream:prompt_cache_keyis mapped to Fireworksprompt_cache_isolation_keyprompt_cache_retentionis removedverbosityis removedstoreis removedweb_search_optionsis removed
Example
2. Responses API
Fireworks Responses use the native Fireworks endpoint:previous_response_idmax_tool_callsstore- native responses streaming
use_anthropic_endpoints enabled on the key or alias, Responses are converted to the Anthropic Messages format and sent to /v1/messages instead. See Anthropic-Compatible Endpoints.
Example
previous_response_id.
3. Text Completions
Fireworks text completions are sent to the native completions endpoint:Example
prompt_cache_key from extra_params and maps it to Fireworks prompt_cache_isolation_key.
4. Embeddings
Fireworks embeddings are sent to:Example
prompt_template, return_logits, and normalize. This page describes the standard embeddings flow currently covered by Bifrost.
5. Unsupported Features
The following operations are still unsupported by the Fireworks provider in Bifrost:6. Caveats
Prompt Caching Semantics
Prompt Caching Semantics
For Fireworks chat completions, Bifrost maps
prompt_cache_key to Fireworks prompt_cache_isolation_key, which is the Fireworks body field for cache isolation. Fireworks also accepts the header form x-prompt-cache-isolation-key. For text completions, Bifrost extracts prompt_cache_key from extra_params and maps it to the same Fireworks body field. If you need Fireworks session-affinity behavior, pass user, configure x-session-affinity in provider extra headers, or send it through the HTTP gateway via x-bf-eh-x-session-affinity. Live cache-hit behavior remains model and deployment dependent.Reasoning History
Reasoning History
Bifrost preserves assistant
reasoning_content for Fireworks chat models that support reasoning history. Fireworks-specific reasoning controls such as reasoning_history are not given special typed handling in this provider page.